
앤트로픽(Anthropic)의 특허 톺아보기
앤트로픽(Anthropic)이 가진 미국 등록특허는 2026년 11월 19일 현재 40건입니다. 공개된 특허 기록에서는 앤트로픽이 직접 개발해 출원한 특허를 찾을 수 없었습니다. 40건 모두 다른 회사에서 넘겨받았습니다. 6건은 2025년 4월 어뎁트 AI 랩스(Adept AI Labs)에서, 34건은 2025년 5월과 2026년 9월 두 차례에 걸쳐 IBM에서 왔습니다. 어뎁트 특허는 화면을 보고 마우스와 키보드를 대신 움직이는 AI 에이전트 기술입니다. IBM 특허는 자연어 처리, 외부 프로그램 연동, 모델 경량화, AI 보안, 음성 인식까지 넓게 걸쳐 있습니다. 앤트로픽은 특허를 하나씩 출원해 쌓기보다 이미 등록된 권리를 사들이는 길을 택했습니다. 파인특허법률사무소는 AI 기업이라면 특허가 투자, 인수, 대출 협상에서 자산으로 평가된다는 점을 염두에 두고 논문이나 블로그로 기술을 공개하기 전에 출원부터 해 두기를 권합니다.
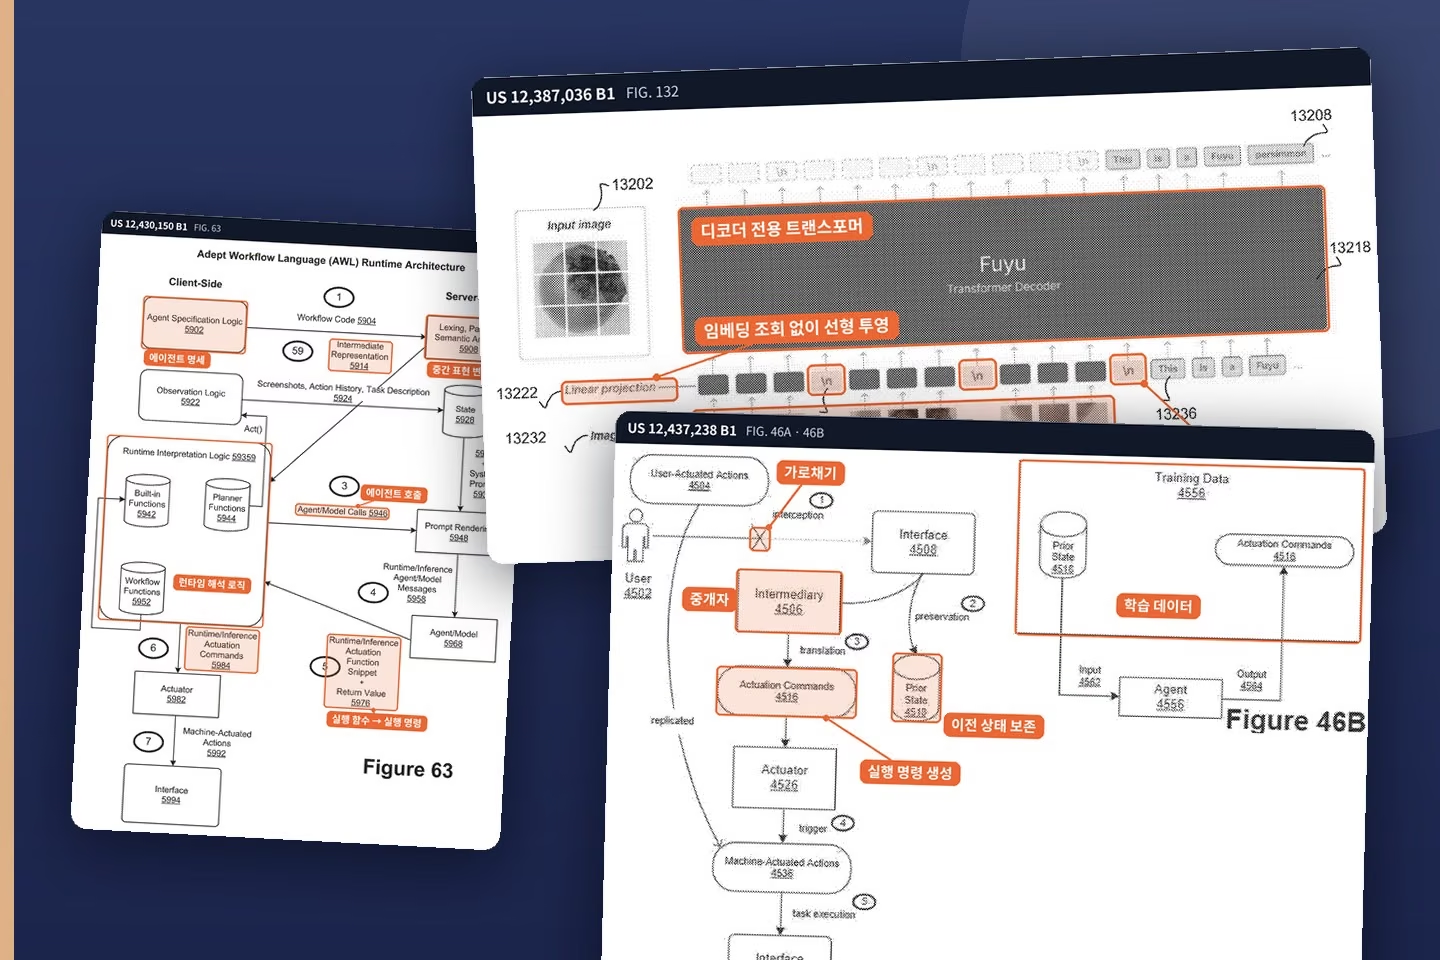
1. 앤트로픽 특허 개요
앤트로픽 명의 특허는 미국 특허청의 양도 기록으로 확인했습니다. 양수인을 앤트로픽으로 검색하면 11건의 기록이 나오고 그중 권리가 실제로 넘어온 큰 거래는 세 번입니다.
첫째는 2025년 4월 8일 어뎁트 AI 랩스와의 양도 계약입니다. 미국 정규출원 8건과 가출원 8건, PCT 출원 1건이 넘어왔습니다. 정규출원 8건 가운데 6건은 등록됐고 2건은 아직 심사 중입니다.
둘째는 2025년 5월 21일 IBM과의 1차 양도입니다. 등록특허 21건, 심판 단계에 있던 출원 1건, 가출원 1건이 넘어왔습니다. 심판 단계의 출원은 2026년 7월 14일 앤트로픽 이름으로 등록됐습니다(US 12,682,280 B2).
셋째는 2026년 9월 4일 IBM과의 2차 양도로, 등록특허 12건이 더해졌습니다. 이 양도는 9월 11일 특허청에 등록됐는데 아직 Google Patents의 현재 권리자 정보에는 반영되지 않았습니다. 그래서 Google Patents에서만 검색하면 앤트로픽 특허가 28건으로 나옵니다.
IBM 1차분 22건에는 2025년 7월 8일 담보권(security interest)도 등록됐습니다. 담보권자는 담보대리인(collateral agent) 자격의 모건스탠리 시니어 펀딩(Morgan Stanley Senior Funding, Inc.)입니다. 계약일은 2025년 5월 14일로 적혀 있습니다. 이틀 뒤인 5월 16일에는 앤트로픽이 모건스탠리 등 7개 은행과 25억 달러 규모의 회전 신용한도(revolving credit facility) 계약을 맺었다는 보도가 나왔습니다. 공개 기록만으로 두 사실을 묶어 단정할 수는 없지만 넘겨받은 특허가 금융 거래의 담보로 잡혀 있다는 사실은 기록에 남아 있습니다.
한국에도 앤트로픽 명의 특허가 1건 있습니다. IBM이 2022년 4월 한국에 진입시킨 국제출원(10-2022-7013741)을 넘겨받아 2025년 7월 출원인을 바꿨습니다. 이 출원은 2026년 1월 21일 제10-2914804호로 등록공고됐습니다. 등록공고 일주일 전인 1월 14일에는 분할출원(10-2026-7001326)도 냈습니다. 국내 기록에는 권리자 이름이 '엔트로픽, 피비씨'로 적혀 있습니다.
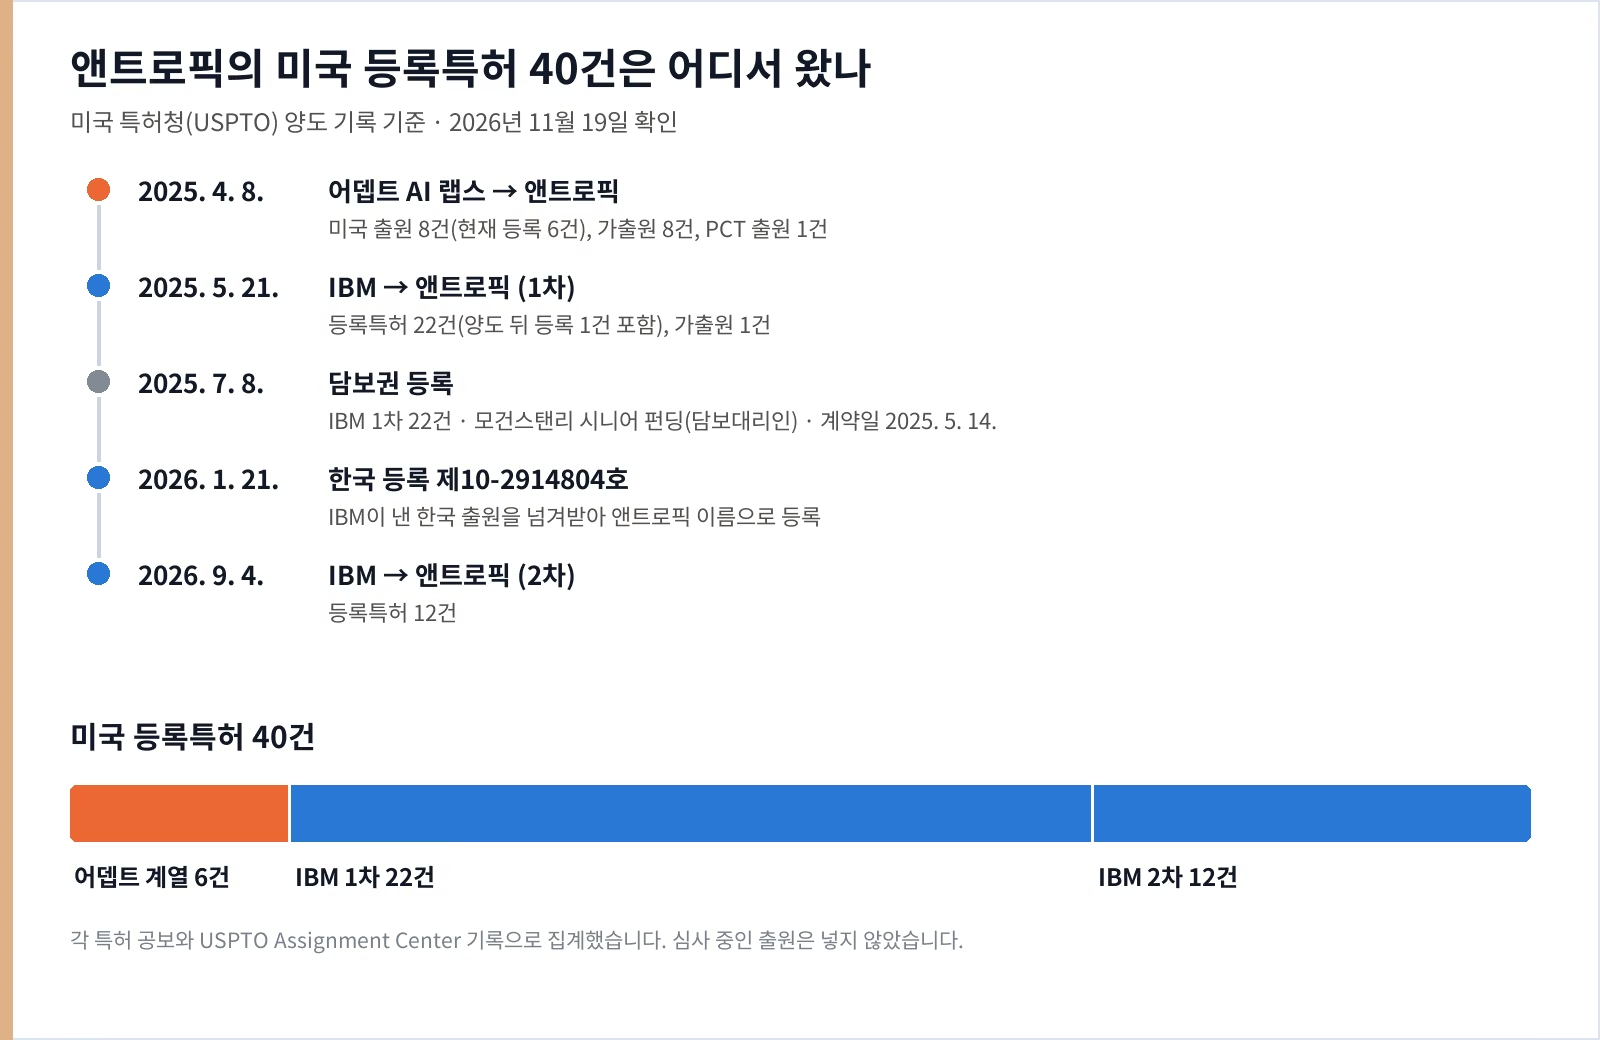
아래 표는 앤트로픽이 보유한 미국 등록특허 40건입니다. 발명의 명칭은 공보에 적힌 원문 그대로 옮겼습니다.
| 등록번호 | 발명의 명칭 | 출원번호 | 등록일 |
|---|---|---|---|
| US 12,387,036 B1 | Multimodal agent for efficient image-text interface automation | 18/909,588 | 2025. 8. 12. |
| US 12,430,150 B1 | Runtime architecture for interfacing with agents to automate multimodal interface workflows | 18/909,455 | 2025. 9. 30. |
| US 12,437,238 B1 | Generation of agentic trajectories for training artificial intelligence agents to automate multimodal interface task workflows | 18/908,447 | 2025. 10. 7. |
| US 12,566,913 B2 | Artificial intelligence agents to automate multimodal interface task workflows | 18/909,068 | 2026. 3. 3. |
| US 12,585,862 B2 | Training data for training artificial intelligence agents to automate multimodal software usage | 18/909,470 | 2026. 3. 24. |
| US 12,619,815 B2 | Magnitude invariant multimodal agent for efficient image-text interface automation | 18/909,558 | 2026. 5. 5. |
| 분야 | 등록번호 | 발명의 명칭 | 양도 |
|---|---|---|---|
| 자연어 처리 | US 9,015,730 B1 | Natural language access to application programming interfaces | 2차 |
| 자연어 처리 | US 9,092,276 B2 | Natural language access to application programming interfaces | 2차 |
| 자연어 처리 | US 11,625,609 B2 | Integration of external applications into deep neural networks | 1차 |
| 자연어 처리 | US 11,763,082 B2 | Accelerating inference of transformer-based models | 1차 |
| 자연어 처리 | US 10,977,439 B2 | Controllable style-based text transformation | 1차 |
| 자연어 처리 | US 11,734,509 B2 | Controllable style-based text transformation | 1차 |
| 자연어 처리 | US 11,361,571 B1 | Term extraction in highly technical domains | 1차 |
| 자연어 처리 | US 11,423,042 B2 | Extracting information from unstructured documents using natural language processing and conversion of unstructured documents into structured documents | 1차 |
| 자연어 처리 | US 11,392,753 B2 | Navigating unstructured documents using structured documents including information extracted from unstructured documents | 1차 |
| 자연어 처리 | US 11,989,237 B2 | Natural language interaction with automated machine learning systems | 2차 |
| 자연어 처리 | US 11,687,385 B2 | Unsupervised event extraction | 2차 |
| 자연어 처리 | US 12,001,896 B2 | Unsupervised event extraction | 2차 |
| 자연어 처리 | US 10,679,000 B2 | Interpreting conversational authoring of information models | 2차 |
| 자연어 처리 | US 11,580,416 B2 | Improving the accuracy of a compendium of natural language responses | 2차 |
| 자연어 처리 | US 11,436,487 B2 | Joint embedding of corpus pairs for domain mapping | 2차 |
| 자연어 처리 | US 10,579,940 B2 | Joint embedding of corpus pairs for domain mapping | 2차 |
| 자연어 처리 | US 11,487,827 B2 | Extended query performance prediction framework utilizing passage-level information | 2차 |
| 자연어 처리 | US 11,790,015 B2 | Extended query performance prediction framework utilizing passage-level information | 2차 |
| 자연어 처리 | US 11,901,047 B2 | Medical visual question answering | 2차 |
| AI 보안·신뢰성 | US 11,520,829 B2 | Training a question-answer dialog sytem to avoid adversarial attacks | 1차 |
| AI 보안·신뢰성 | US 11,755,657 B2 | Training a question-answer dialog system to avoid adversarial attacks | 1차 |
| AI 보안·신뢰성 | US 11,501,156 B2 | Detecting adversarial attacks through decoy training | 1차 |
| AI 보안·신뢰성 | US 11,829,879 B2 | Detecting adversarial attacks through decoy training | 1차 |
| AI 보안·신뢰성 | US 11,586,849 B2 | Mitigating statistical bias in artificial intelligence models | 1차 |
| AI 보안·신뢰성 | US 11,037,049 B2 | Determining rationale of cognitive system output | 1차 |
| 학습 효율·프라이버시 | US 10,949,746 B2 | Efficient parallel training of a network model on multiple graphics processing units | 1차 |
| 학습 효율·프라이버시 | US 11,010,637 B2 | Generative adversarial network employed for decentralized and confidential AI training | 1차 |
| 학습 효율·프라이버시 | US 11,676,011 B2 | Private transfer learning | 1차 |
| 학습 효율·프라이버시 | US 11,443,235 B2 | Identifying optimal weights to improve prediction accuracy in machine learning techniques | 1차 |
| 학습 효율·프라이버시 | US 12,682,280 B2 | Identifying optimal weights to improve prediction accuracy in machine learning techniques | 1차 |
| 음성 인식 | US 11,158,303 B2 | Soft-forgetting for connectionist temporal classification based automatic speech recognition | 1차 |
| 음성 인식 | US 11,183,194 B2 | Detecting and recovering out-of-vocabulary words in voice-to-text transcription systems | 1차 |
| 음성 인식 | US 11,783,811 B2 | Accuracy of streaming RNN transducer | 1차 |
| 음성 인식 | US 12,288,551 B2 | Accuracy of streaming RNN transducer | 1차 |
2. 어뎁트에서 넘어온 에이전트 특허 6건
어뎁트는 OpenAI 엔지니어링 부사장 출신 데이비드 루안(David Luan) 등이 세운 회사로, 사람 대신 소프트웨어를 조작하는 AI 에이전트를 개발했습니다. 2024년 6월에는 아마존이 루안을 비롯한 공동창업자 일부를 영입하고 어뎁트 기술에 대한 비독점 라이선스를 받았다고 보도됐습니다. 어뎁트는 남은 인력으로 회사를 이어 갔습니다.
앤트로픽이 넘겨받은 6건은 모두 2024년 3월 20일과 4월 25일에 낸 미국 가출원을 기초로, 같은 해 10월 7일과 8일 한꺼번에 낸 정규출원에서 나왔습니다. 6건이 FIG. 1부터 FIG. 174까지 같은 명세서와 도면을 쓰고 청구항만 나눠 서로 다른 부분을 권리로 잡았습니다. 가장 먼저 등록된 US 12,387,036 B1은 출원 10개월 만에 등록됐습니다.
앤트로픽은 2024년 10월 22일 '컴퓨터 사용(computer use)' 기능을 공개 베타로 내놓았습니다. 클로드가 화면을 보고 커서를 옮기고 클릭과 입력을 하는 기능입니다. 어뎁트 특허가 다루는 영역이 바로 이런 에이전트입니다. 다만 앤트로픽 제품이 이 특허 기술을 그대로 쓰는지는 공개 자료로 확인되지 않습니다.
(1) 화면 이미지를 줄 단위 토큰으로 읽는 멀티모달 에이전트
US 12,387,036 B1 · 원제 Multimodal agent for efficient image-text interface automation · 출원 2024. 10. 8. · 등록 2025. 8. 12.
목적
- 스크린샷처럼 크기와 해상도가 제각각인 화면 이미지를 텍스트와 함께 처리하는 에이전트를 단순한 구조로 만듭니다.
- 이미지 인코더를 따로 두지 않고 언어 모델 하나로 화면을 읽게 합니다.
핵심 솔루션
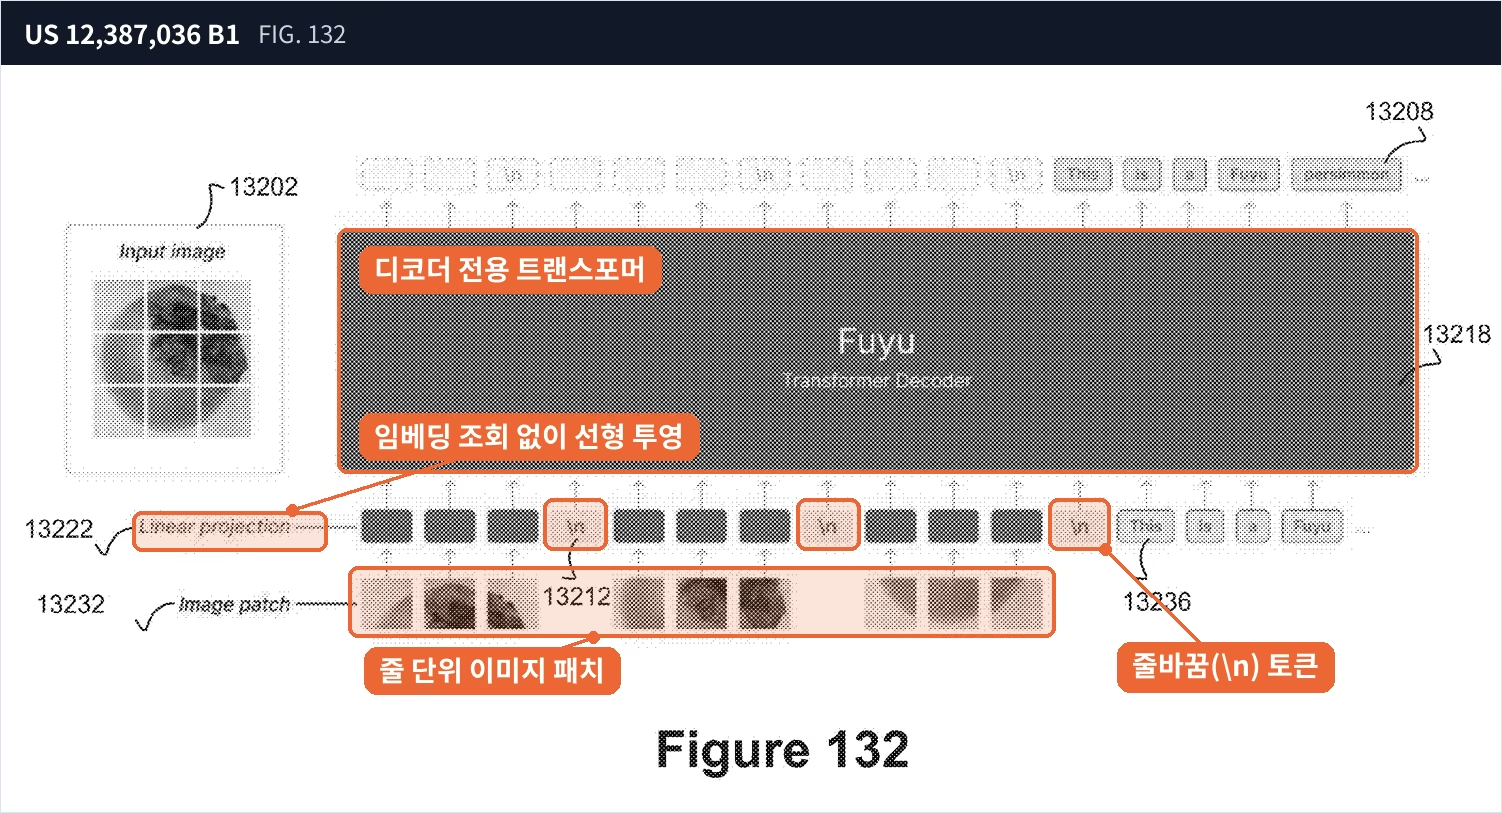
- 입력 이미지를 줄(행) 단위로 잘라 패치를 늘어놓고 한 줄이 끝날 때마다 줄바꿈 문자(\n)를 넣어 이미지의 가로·세로 구조를 알려 줍니다.
- 텍스트 토큰과 이미지 토큰을 하나의 토큰 열로 합친 뒤, 임베딩 조회(embedding lookup)를 거치지 않고 선형 투영으로 디코더 전용 트랜스포머에 넣습니다.
- 도면 FIG. 132에는 'Fuyu Transformer Decoder'라는 이름이 적혀 있습니다. 어뎁트가 2023년 10월 공개한 멀티모달 모델 Fuyu-8B의 구조를 담은 그림으로 보입니다.
활용 예시
- 화면 질의응답: 웹페이지 스크린샷을 보고 로그인 버튼이 어디 있는지 찾아 좌표로 답하는 에이전트
- 해상도가 다른 화면 처리: 노트북 화면과 휴대전화 화면을 크기 조정 없이 같은 모델로 읽는 업무 자동화 도구
대표 청구항 1
1. A system for image-text agentic interface automation, comprising:
a multimodal agent configured to process arbitrary-length text sequences and arbitrary-resolution images:
memory storing an input image and an input text sequence;
patch extraction logic configured to extract image patches from the input image on a line-by-line basis, and generate a plurality of lines of image patches for the input image;
newline insertion logic configured to interleave a newline character between successive lines of image patches in the plurality of lines of image patches, wherein the newline character specifies an end of a line in the input image;
tokenization logic configured to translate the input text sequence into a sequence of input text tokens, and to translate the successive lines of image patches interleaved with the newline character into a sequence of input image tokens;
linear projection logic configured to linearly project a single token stream of the sequence of input text tokens and the sequence of input image tokens into a decoder-only Transformer logic, wherein the linear projection of the single token stream bypasses any embedding lookup; and
the decoder-only Transformer logic configured to process the linearly projected, embedding lookup-bypassed single token stream to generate a sequence of output tokens that are responsive to the input image and the input text sequence.
청구항에서 볼 점
청구항 1은 줄 단위 패치 추출, 줄바꿈 문자 삽입, 임베딩 조회를 거치지 않는 선형 투영, 디코더 전용 트랜스포머를 모두 요구합니다. 별도의 이미지 인코더로 특징을 뽑아 언어 모델에 넘기는 흔한 멀티모달 구조는 이 문언과 거리가 있습니다. 반대로 패치를 그대로 디코더에 넣는 모델이라면 줄바꿈 토큰을 쓰는지부터 살펴봐야 합니다.
(2) 이미지 패치를 1과 -1의 비트로 바꿔 넣는 변형
US 12,619,815 B2 · 원제 Magnitude invariant multimodal agent for efficient image-text interface automation · 출원 2024. 10. 8. · 등록 2026. 5. 5.
목적
- (1)과 같은 구조에서 이미지 패치의 값을 크기(magnitude)에 흔들리지 않는 형태로 바꿔 넣습니다.
핵심 솔루션
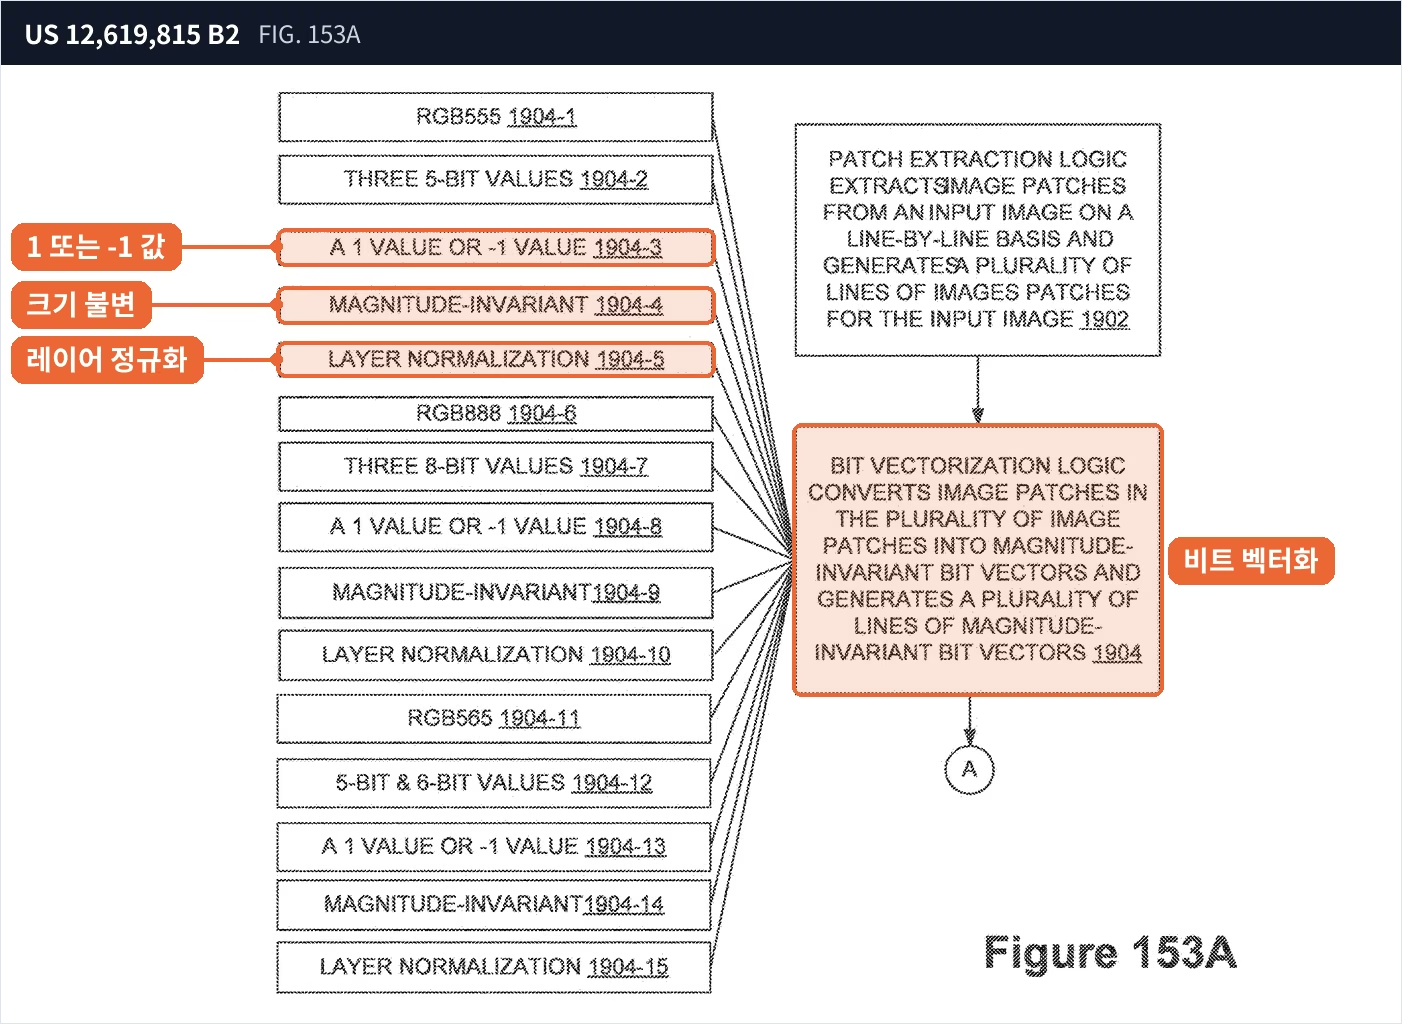
- 패치의 픽셀 값을 RGB555, RGB888, RGB565 같은 형식으로 압축해 비트로 바꾸고 각 비트를 1 또는 -1로 나타냅니다(FIG. 153A).
- 명세서는 이렇게 만든 값이 레이어 정규화(LayerNorm) 같은 디코더의 스케일 조정 함수에 대해 크기 불변이라고 설명합니다.
- 줄바꿈 토큰, 임베딩 조회 없는 선형 투영, 디코더 전용 트랜스포머는 (1)과 같습니다.
활용 예시
- 화면 이해 에이전트의 입력 표현: 픽셀 값을 실수 그대로 넣는 대신 압축한 비트 벡터로 넣는 설계
- 입력 형식 선택: 색마다 5비트를 쓰는 RGB555, 8비트를 쓰는 RGB888, 초록에만 6비트를 쓰는 RGB565 가운데 하나를 골라 쓰는 구성
대표 청구항 1
1. A system for magnitude-invariant image-text agentic interface automation, comprising:
memory storing an input image and an input text sequence;
patch extraction logic configured to extract image patches from the input image on a line-by-line basis, and generate a plurality of lines of image patches for the input image;
bit vectorization logic configured to convert image patches in the plurality of lines of image patches into magnitude-invariant bit vectors, and generate a plurality of lines of magnitude-invariant bit vectors;
newline insertion logic configured to interleave a newline character between successive lines of magnitude-invariant bit vectors in the plurality of lines of magnitude-invariant bit vectors, wherein the newline character specifies an end of a line in the input image;
tokenization logic configured to translate the input text sequence into a sequence of input text tokens, and to translate the successive lines of magnitude-invariant bit vectors interleaved with the newline character into a sequence of input magnitude-invariant bit vector tokens;
linear projection logic configured to linearly project a single token stream of the sequence of input text tokens and the sequence of input magnitude-invariant bit vector tokens into a decoder-only Transformer logic, wherein the linear projection of the single token stream bypasses any embedding lookup; and
the decoder-only Transformer logic configured to process the linearly projected, embedding lookup-bypassed single token stream to generate a sequence of output tokens that are responsive to the input image and the input text sequence.
청구항에서 볼 점
(1)의 구성에 '크기 불변 비트 벡터로 바꾸는 비트 벡터화 로직'이 더해져 권리범위는 (1)보다 좁습니다. 같은 명세서에서 기본 구조와 세부 변형을 따로 등록받아 권리를 겹겹이 쌓은 예입니다. 이 특허에는 2026년 7월 14일 정정증명서가 나왔지만 고친 곳은 명세서의 도면 설명과 부호이고 청구항은 그대로입니다.
(3) 8종 데이터로 학습한 화면 조작 에이전트
US 12,585,862 B2 · 원제 Training data for training artificial intelligence agents to automate multimodal software usage · 출원 2024. 10. 8. · 등록 2026. 3. 24.
목적
- 소프트웨어 화면을 보고 사용자의 요청을 단계별 조작으로 옮기는 비전 언어 모델 에이전트를 만들고 무엇으로 학습시키는지를 구체적으로 정합니다.
핵심 솔루션
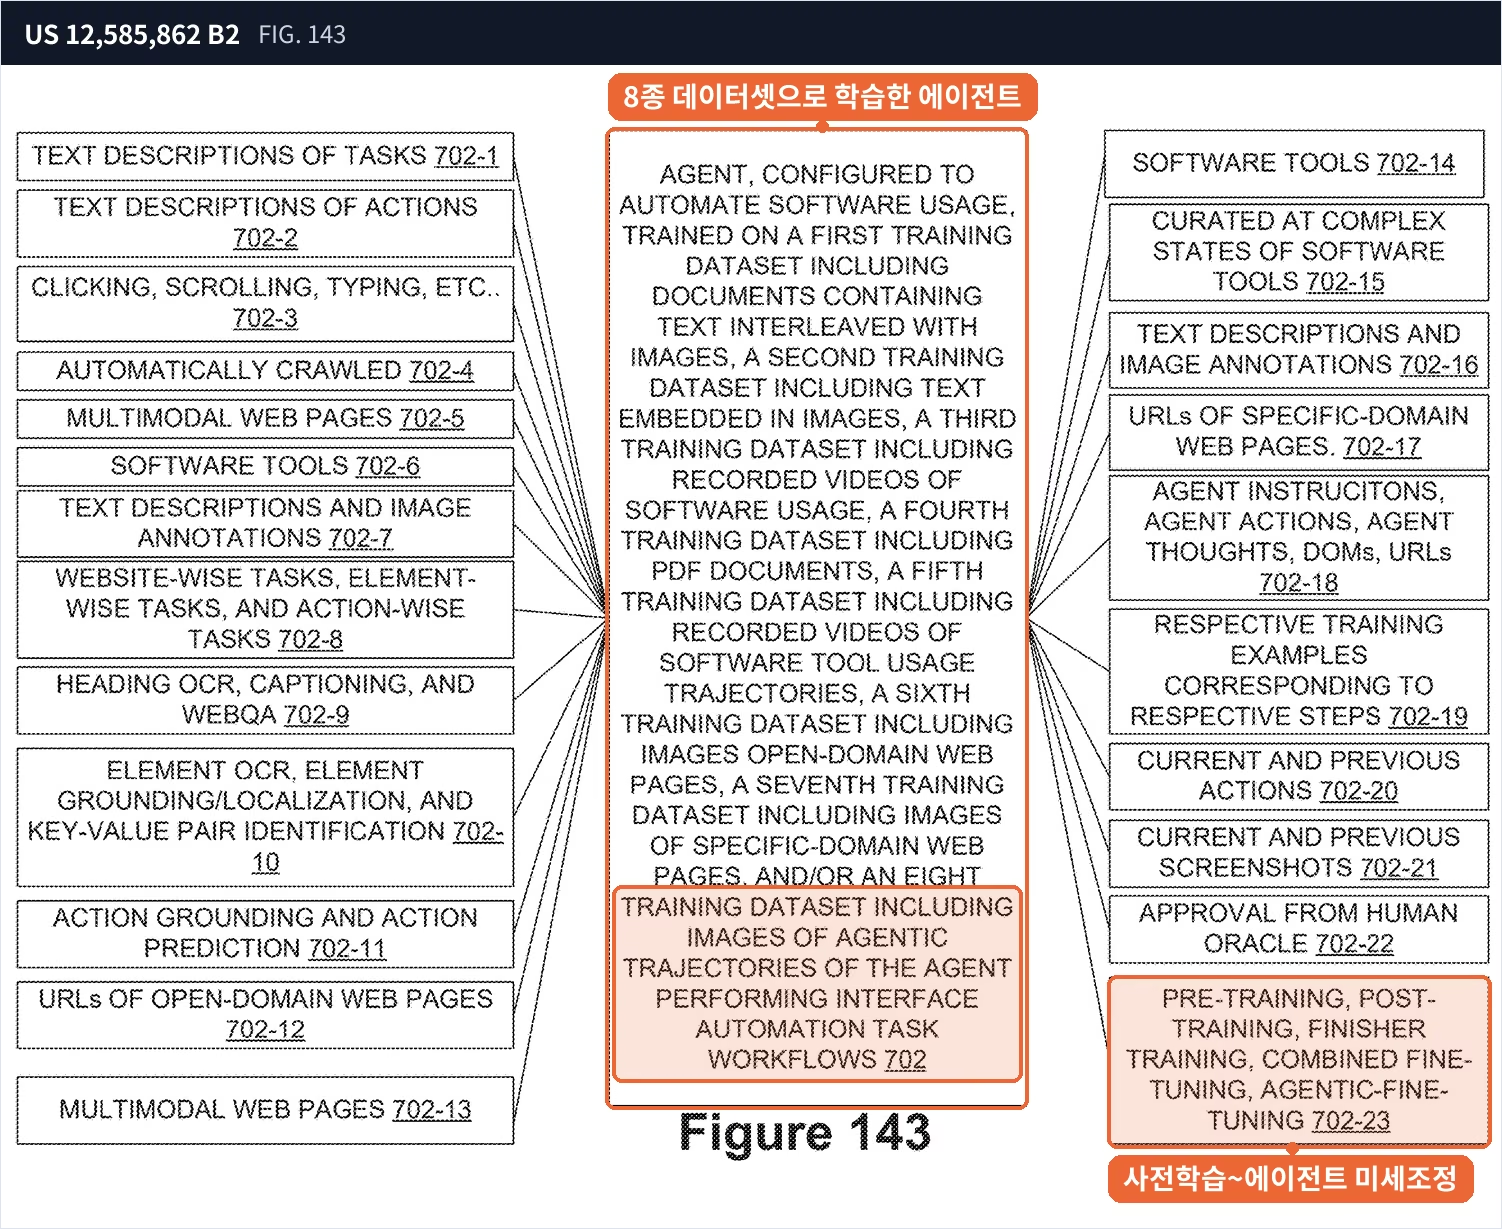
- 트랜스포머 기반 비전 언어 모델을 8종의 데이터로 학습합니다. 글과 이미지가 섞인 문서, 이미지 속 글자, 소프트웨어 사용 녹화 영상, PDF 문서, 소프트웨어 도구 사용 궤적 영상, 일반 웹페이지 이미지, 특정 분야 웹페이지 이미지, 에이전트 자신의 작업 궤적 이미지입니다.
- 사용자가 자연어로 원하는 일을 말하면, 모델이 현재 스크린샷과 요청을 보고 직전 행동과 다음 행동을 담은 작업 흐름(workflow)을 만듭니다.
- 에이전트가 다음 행동을 실행해 화면이 바뀌면 바뀐 화면의 스크린샷으로 다음 명령을 다시 만들고 작업이 끝날 때까지 이를 반복합니다.
활용 예시
- 업무 자동화: "지난달 청구서를 회계 프로그램에 입력해 줘" 같은 요청을 받아 웹 화면을 차례로 조작하는 에이전트
- 학습 데이터 수집: 사람이 남긴 소프트웨어 사용 녹화 영상을 모아 에이전트 학습에 쓰는 데이터 파이프라인
대표 청구항 1
1. A system for automating actions on a software user interface, comprising:
a processor; and
a memory storing instructions which, when executed, cause the processor to perform steps comprising:
constructing an artificial intelligence agent based on a Transformer based vision language model configured to automate actions on a software user interface, including training the Transformer based vision language model on:
a first training dataset including documents containing text interleaved with images;
a second training dataset including text embedded in images;
a third training dataset including recorded videos of software usage;
a fourth training dataset including portable document format (PDF) documents;
a fifth training dataset including recorded videos of software tool usage trajectories;
a sixth training dataset including images of open-domain web pages;
a seventh training dataset including images of specific-domain web pages; and
an eighth training dataset including images of agentic trajectories of the agent performing interface automation task workflows;
receiving, via a user interface, a natural language input indicating a user intent to interact with the software user interface;
generating, by the Transformer based vision language model, a workflow indicating a past action and a next action relating to the user intent based on an input comprising a screenshot of the software user interface and the natural language input;
executing, by the artificial intelligence agent, at least the next action in a form of a machine-actuated command on the software user interface thereby resulting in a change in the software user interface; and
iteratively generating, by the Transformer based vision language model, next machine-actuated commands based on a screenshot of a changed software user interface; and
iteratively executing, by the artificial intelligence agent, the next machine-actuated commands thereby causing a task described by the natural language input to be completed by interacting with the software user interface.
청구항에서 볼 점
청구항은 학습 데이터 8종을 모두 나열합니다. 문언대로라면 이 가운데 하나라도 쓰지 않은 모델에는 문언 침해를 주장하기 어려워 범위가 넓은 특허는 아닙니다. 또 학습 데이터 구성은 제품만 봐서는 알기 어려워 침해를 입증할 증거를 모으기도 쉽지 않습니다. 학습 데이터를 청구항에 적으면 이런 한계가 생깁니다.
(4) 사람의 조작을 가로채 학습 데이터로 만드는 중개자
US 12,437,238 B1 · 원제 Generation of agentic trajectories for training artificial intelligence agents to automate multimodal interface task workflows · 출원 2024. 10. 7. · 등록 2025. 10. 7.
목적
- 사람이 소프트웨어를 쓰는 과정을 그대로 에이전트 학습 데이터로 바꿉니다.
핵심 솔루션
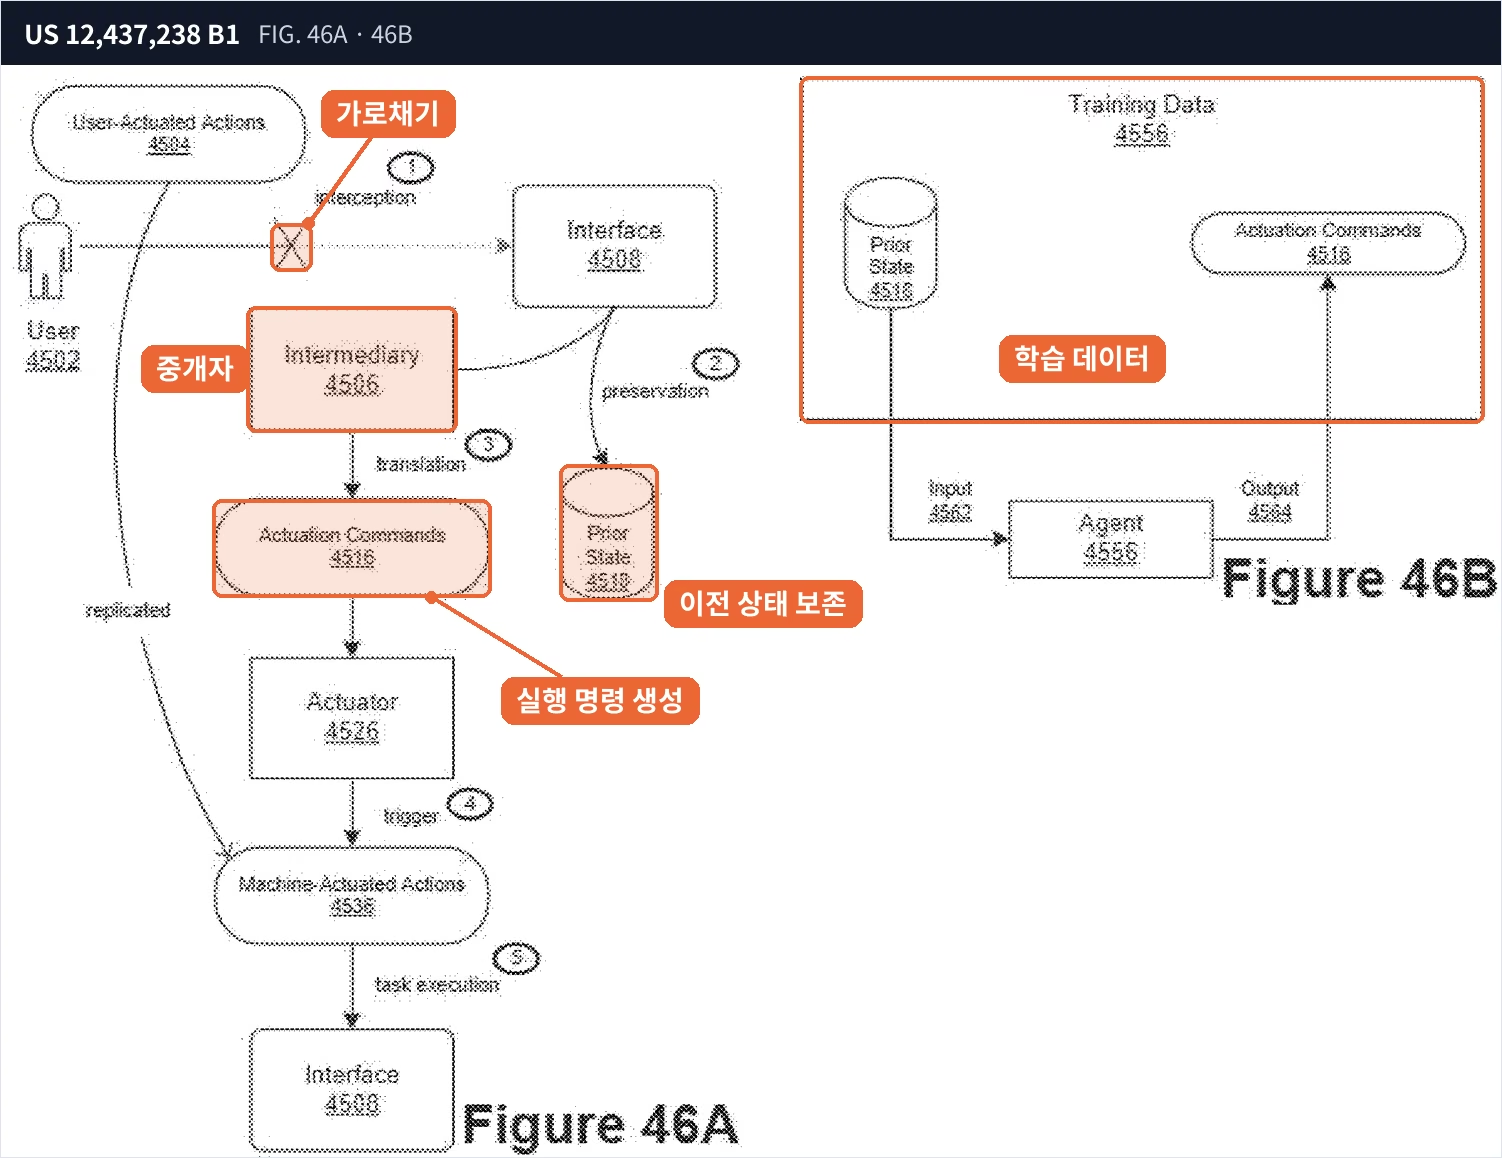
- 사용자와 화면(인터페이스) 사이에 중개자(intermediary)를 두고 사용자의 클릭과 입력을 가로챕니다(FIG. 46A의 ①).
- 조작이 실행되기 전의 화면 상태를 텍스트와 이미지째 보존합니다(②).
- 가로챈 조작을 멀티헤드 어텐션을 쓰는 트랜스포머 기반 멀티모달 신경망에 넣어 실행 명령(actuation command)으로 번역하고(③) 이 명령으로 같은 조작을 기계가 재현합니다.
- '실행 전 화면 상태 → 실행 명령' 쌍을 학습 데이터로 쌓습니다(FIG. 46B). 번역과 생성은 클라이언트 기기에서 도는 런타임 해석 로직이 맡습니다.
활용 예시
- 사내 업무 기록: 직원이 업무 시스템을 쓰는 동안 브라우저 확장 프로그램이 조작을 기록해 자동화 에이전트의 학습 데이터를 만드는 방식
- 사람의 단계별 교정: 명세서의 레코더(Recorder) 도구(FIG. 44, FIG. 45)처럼 사람이 단계마다 에이전트 행동을 고쳐 주며 데이터를 모으는 방식
대표 청구항 1
1. A system for generating training data to train agents to automate multimodal interface task workflows, comprising:
an intermediary interposed between an interface, comprising multimodal content, and a user, and the intermediary is configured to:
intercept one or more user-actuated actions directed towards the interface by the user, wherein the user-actuated actions, if received by the interface, execute a task on the interface;
preserve a state of the interface prior to the execution of the task, wherein the preserved state includes multimodal data comprising arbitrary-length text sequences and arbitrary-resolution images;
translate the user-actuated actions into one or more actuation commands using a transformer-based multimodal neural network comprising multi-head attention mechanisms, wherein the actuation commands are configured to trigger one or more machine-actuated actions that replicate the user-actuated actions on the interface to cause automation of the multimodal task workflow; and
generate a multimodal training dataset to train an agent to automate the task, wherein the training dataset requires the agent to process, as input, the multimodal state of the interface prior to the execution of the task, and to generate, as output, the actuation commands, wherein the translation and generation are performed using runtime interpretation logic dynamically executing on a client-side computing device.
청구항에서 볼 점
사용자와 화면 사이에 끼어드는 중개자, 그리고 클라이언트 기기에서 동적으로 실행되는 런타임 해석 로직이 함께 요구됩니다. 앞선 칼럼에서 본 OpenAI의 비디오 학습 특허처럼 화면 녹화 영상에서 행동을 사후에 추정하는 방식과는 접근이 다릅니다.
(5) 작업을 쪼개고 전용 언어로 명령하는 에이전트
US 12,566,913 B2 · 원제 Artificial intelligence agents to automate multimodal interface task workflows · 출원 2024. 10. 8. · 등록 2026. 3. 3.
목적
- 자연어 설명과 구체적인 지시를 함께 받아 여러 단계의 화면 작업을 끝까지 수행하는 에이전트를 만듭니다.
핵심 솔루션
- 입력에는 자연어 작업 설명, 구체적 지시(prescriptive command), 맥락 정보, 실행 전 화면 상태가 들어갑니다.
- 작업을 앞 단계가 끝나야 다음 단계로 넘어가는 하위 작업으로 나눕니다.
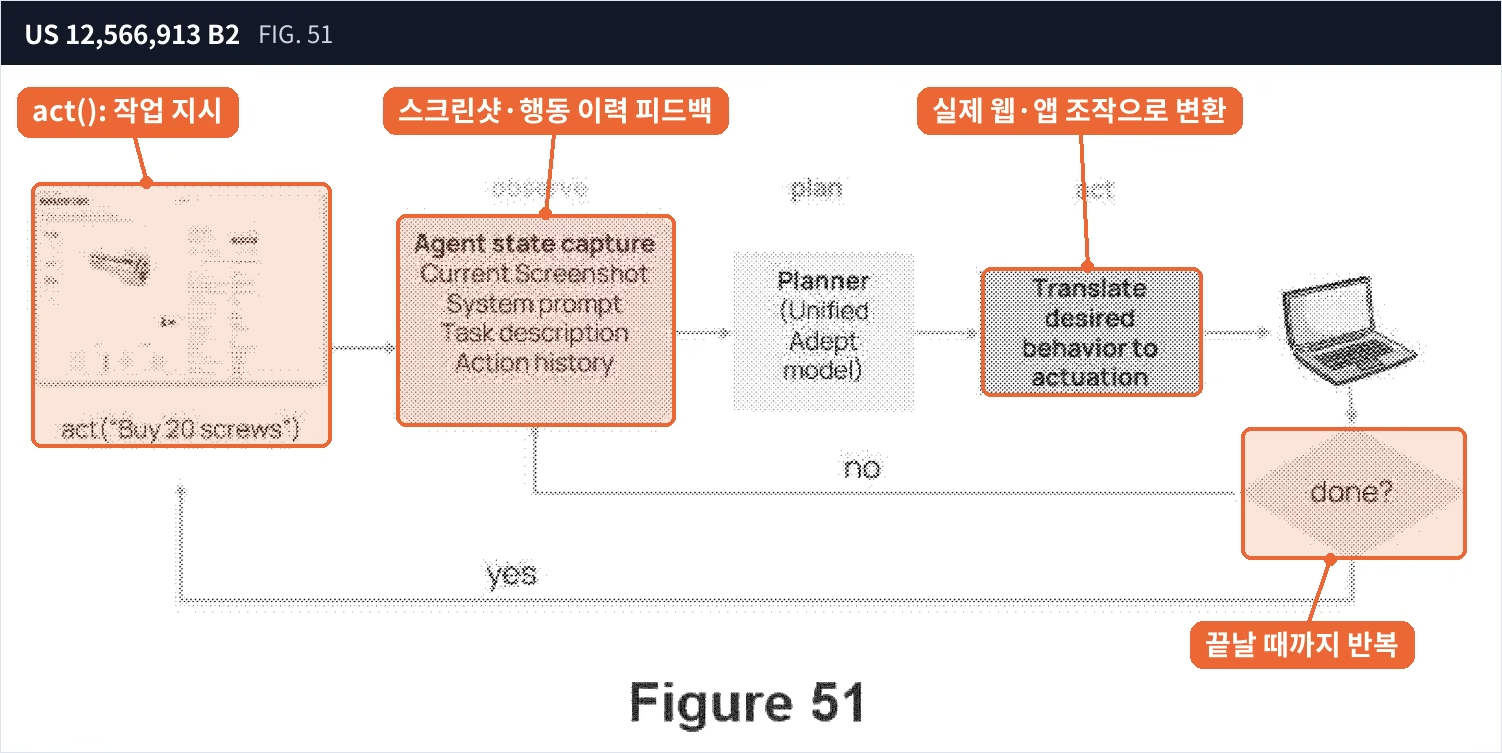
- 실행 명령은 모델 호출과 행동 실행을 모두 지원하는 자체 도메인 특화 언어(DSL)로 표현합니다. 명세서의 어뎁트 워크플로 언어(AWL)와 act() 함수가 그 예입니다(FIG. 51).
- 모델의 지시를 실제 웹·앱 이벤트로 바꾸며 화면 요소의 위치를 찾는 로컬라이제이션(localization)도 포함합니다.
- 스크린샷과 행동 이력을 피드백으로 받아 작업을 되풀이하며 다듬습니다.
활용 예시
- 한 줄 명령 자동화: FIG. 51의 act("Buy 20 screws")처럼 한 줄 명령으로 쇼핑몰 검색부터 주문 단계까지 진행하는 스크립트
- 백오피스 반복 업무: 사내 시스템 여러 개를 오가며 같은 입력을 되풀이하는 작업
대표 청구항 1
1. A system for interface automation, comprising:
at least one central processing unit:
a memory device storing programming and data constructs that when executed by the at least one processing unit, cause the system to configure an agent;
the agent configured to:
process an input including multimodal data that specifies an interface workflow including contextual metadata and a state of the interface prior to execution of the interface workflow, wherein the multimodal data includes at least a combination of a natural language description and a prescriptive command; and
segment the interface workflow into a plurality of sub-tasks wherein each sub-task depends on the completion of a preceding sub-task;
generate an output, responsive to the multimodal input data, that specifies a sequence of actuation commands expressed in a custom domain-specific language (DSL) that supports both model calls and action executions, wherein the sequence of actuation commands triggers one or more machine-actuated actions that replicate user-actuated actions on the interface and cause automation of the interface workflow by translating model instructions into real web or application events, including at least localization;
actuate the sequence of multimodal actuation commands by an actuator, wherein the actuator is configured to receive the sequence of actuation commands from the agent, and to perform the machine-actuated actions based on the sequence of actuation commands as synthetic actions that automate the interface workflow; and
provide feedback including interface screenshots and action histories for iterative workflow execution and refinement.
청구항에서 볼 점
하위 작업 분할, 모델 호출과 행동 실행을 함께 지원하는 DSL, 로컬라이제이션, 스크린샷과 행동 이력 피드백까지 구성요소가 많습니다. 특히 '자체 DSL'은 해석에 따라 범위가 크게 달라질 수 있는 표현입니다. 에이전트 제품을 만드는 기업은 자사 명령 체계가 여기에 해당하는지부터 따져 볼 만합니다.
(6) 사용자 기기에서 돌아가는 에이전트 실행 런타임
US 12,430,150 B1 · 원제 Runtime architecture for interfacing with agents to automate multimodal interface workflows · 출원 2024. 10. 8. · 등록 2025. 9. 30.
목적
- 개발자가 쓴 에이전트 작업 코드를 사용자 기기(클라이언트)에서 실행하는 구조를 만듭니다. 서버의 AI 모델은 판단이 필요할 때만 부릅니다.
핵심 솔루션
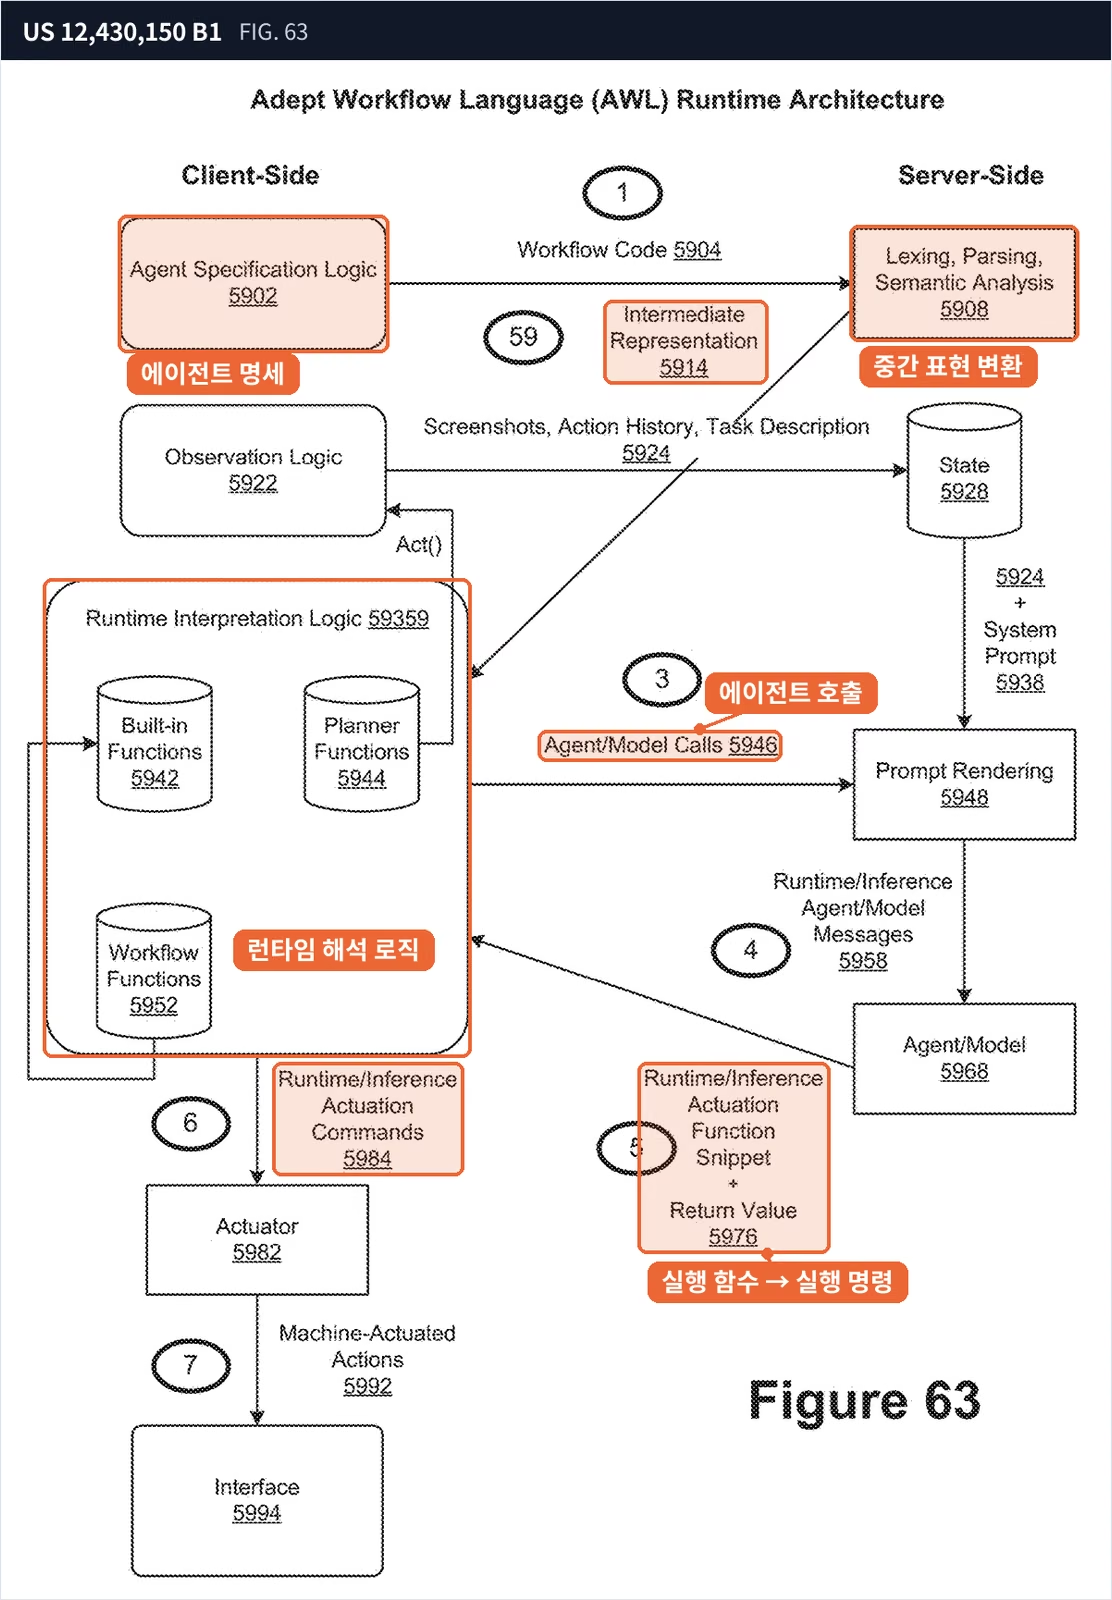
- 클라이언트의 에이전트 명세 로직이 워크플로 코드를 만들어 보내면, 서버가 이를 구문 분석해 중간 표현(intermediate representation)으로 바꿉니다.
- 클라이언트의 런타임 해석 로직이 중간 표현에서 에이전트 함수를 찾아 에이전트 호출을 만들고 모델에 보냅니다.
- 모델이 돌려준 실행 함수(actuation function)를 런타임이 실행 명령으로 바꾸고 액추에이터가 화면에서 기계 조작을 수행합니다(FIG. 63).
활용 예시
- 브라우저 확장형 에이전트: 확장 프로그램 안에서 업무 스크립트를 돌리고 판단이 필요한 단계에서만 클라우드 모델을 부르는 서비스
- 반복 조작의 기기 내 처리: 정해진 클릭과 입력은 사용자 기기에서 바로 처리하고 모델 호출만 서버로 보내는 구성
대표 청구항 1
1. A system, running on one or more processors, for client-side implementation of an interface automation language at runtime, comprising:
agent specification logic, running on client-side, and configured to construct an agent specification, and to make the agent specification available for server-side translation into an intermediate representation, wherein the agent specification is configured to automate a multimodal interface workflow; and
runtime interpretation logic, running on the client-side, and configured to:
receive the intermediate representation;
detect one or more agent functions in the intermediate representation;
generate one or more agent calls based on the agent functions;
issue the agent calls to an agent, and, in response, receive at least one runtime actuation function from the agent; and
translate the runtime actuation function into at least one runtime actuation command, wherein the runtime actuation command triggers at least one machine-actuated action as a runtime synthetic action that automates the multimodal interface workflow.
청구항에서 볼 점
청구항에는 역할 분담이 정해져 있습니다. 에이전트 명세와 런타임 해석은 클라이언트에서, 중간 표현으로 번역하는 일은 서버에서 합니다. 모든 처리를 서버에서 하거나 모든 처리를 기기에서 하는 구조라면 문언과 맞지 않을 수 있습니다. 이 특허를 피하는 설계는 에이전트의 실행 위치를 어떻게 나누느냐에 달려 있습니다.
3. IBM에서 넘어온 특허 34건
IBM 특허 34건은 2013년부터 2023년 사이에 출원됐습니다. 자연어 처리가 19건으로 가장 많고 AI 보안·신뢰성 6건, 학습 효율·프라이버시 5건, 음성 인식 4건입니다. 이 가운데 앤트로픽의 제품 영역과 가까운 4건, 그리고 국내 등록특허 1건의 대표 청구항을 살펴봅니다.
(7) 자연어 요청을 API 호출로 바꾸는 방법
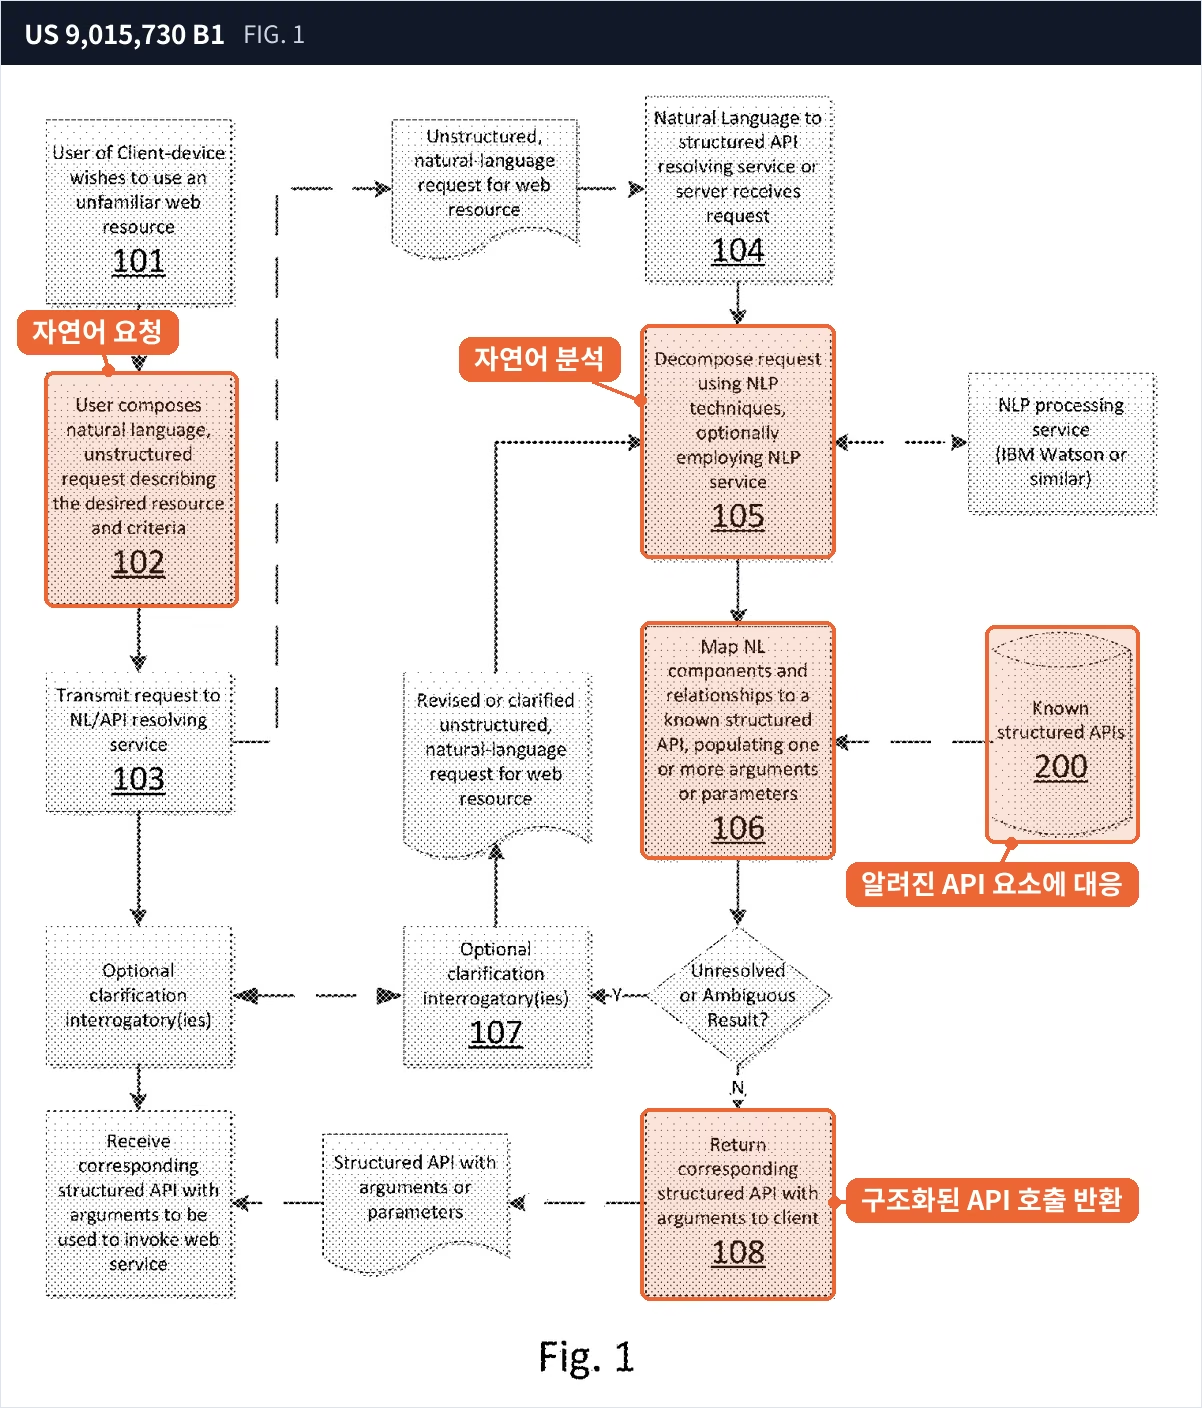
US 9,015,730 B1 · 원제 Natural language access to application programming interfaces · 출원 2013. 12. 17. · 등록 2015. 4. 21. · 2026년 9월 양도
목적
- API 문법을 모르는 사용자도 자연어로 웹 서비스를 쓸 수 있게 합니다.
핵심 솔루션
- 비정형 자연어 요청을 분석해 구성요소를 뽑아내고(FIG. 1의 105), 알려진 구조화 API의 요소에 대응시킵니다(106, 200).
- 구성요소를 API 요소에 맞춰 구조화된 API 호출을 만들고(108) 대신 호출하거나 호출문 또는 결과를 돌려줍니다.
- FIG. 1에는 자연어 분석을 IBM 왓슨(Watson) 같은 서비스에 맡길 수 있다고 적혀 있습니다.
활용 예시
- 도구 호출: 오늘날 대형 언어 모델이 자연어 요청을 받아 외부 API를 부르는 도구 사용(tool use)이나 함수 호출과 같은 흐름입니다.
대표 청구항 1
1. A method for handling a user request for invoking a computer service through an Application Programming Interface, comprising:
receiving by a computer an unstructured request from a client to use or invoke a computer service, wherein the unstructured request comprises natural language (NL) containing one or more NL components;
performing by a computer natural language analysis on the unstructured request to extract one or more of the NL components;
matching by a computer the one or more NL components to one or more elements of at least one Hyper Text Transfer Protocol signature-based structured Application Programming Interface (API), wherein each structured API corresponds to the corresponding computer service, and wherein each API element corresponds to a parameter or argument to invoke the corresponding service;
constructing by a computer a structured API call by mapping the one or more extracted NL components to one or more of the API elements; and
performing by a computer one or more operations selected from the group consisting of submitting the constructed structured API call to a corresponding computer service on behalf of the client, returning the constructed structured API call to the client, and returning a result from an invoked corresponding computer service to the requesting client.
청구항에서 볼 점
2013년 출원이라 Google Patents가 추정한 만료일은 2033년 12월 17일입니다. 대형 언어 모델이 나오기 전의 특허지만 청구항은 언어 모델의 종류를 묻지 않고 '자연어 분석'과 'HTTP 시그니처 기반 구조화 API'로 적혀 있습니다. 같은 패밀리의 US 9,092,276 B2도 함께 넘어왔습니다.
(8) 학습 때는 추정 레이어, 추론 때는 실제 외부 앱
US 11,625,609 B2 · 원제 Integration of external applications into deep neural networks · 출원 2018. 6. 14. · 등록 2023. 4. 11.
목적
- 외부 소프트웨어는 대개 미분할 수 없어서 신경망과 함께 처음부터 끝까지(end-to-end) 학습시키기 어렵습니다. 이 특허가 푸는 문제입니다.
- 명세서는 'Is 7.2 greater than 4.5?' 같은 질문을 예로 들어 언어 처리는 신경망이 맡고 숫자 비교는 외부 API가 맡는 구성을 설명합니다.
핵심 솔루션
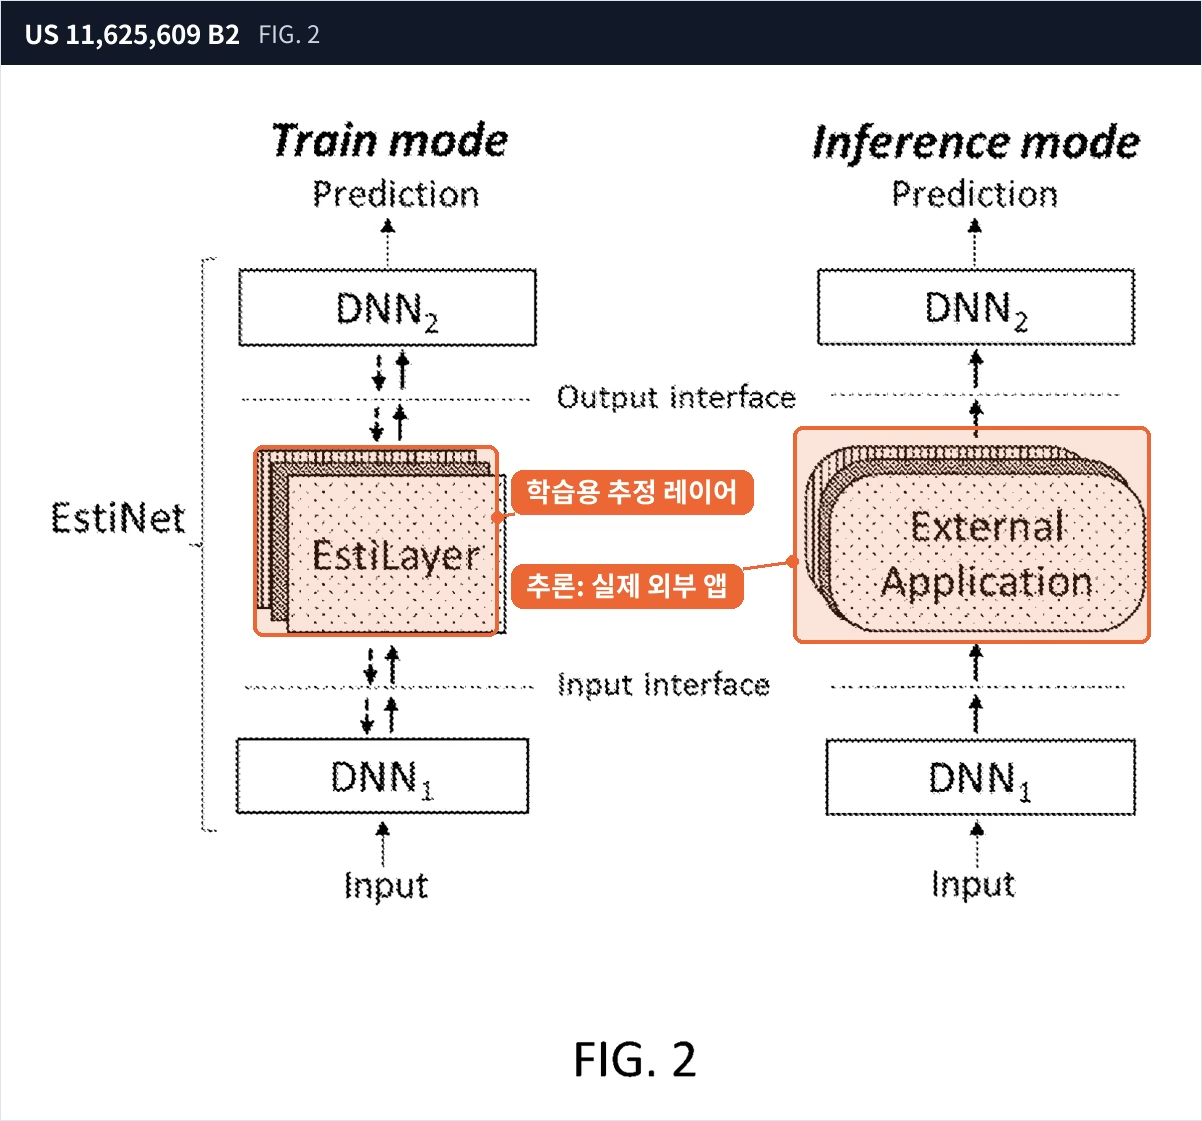
- 학습 때는 외부 앱의 기능을 흉내 내는 미분 가능한 추정 서브네트워크(EstiLayer)를 끼워 넣고 외부 앱 API의 입출력 형식과 특성을 학습합니다.
- 추론 때는 이 서브네트워크를 빼고 학습된 신경망이 외부 앱의 API와 직접 주고받습니다(FIG. 2).
활용 예시
- 외부 도구를 쓰는 모델: 언어 모델이 계산, 검색, 코드 실행 같은 외부 도구를 부르도록 학습시키는 일과 같은 문제를 다룹니다.
대표 청구항 1
1. A method comprising:
during end-to-end training of a Deep Neural Network (DNN), operating a differentiable estimator subnetwork to estimate a functionality of an external software application, wherein the estimation comprises learning an Application Programming Interface (API) of the external software application by learning a format and characteristics of input and output parameters of said API, and wherein said end-to-end training trains said DNN to comply with said estimation by said differentiable estimator subnetwork; and
during inference, operating the trained DNN to interact directly, without using said differentiable estimator subnetwork, with said API, to cause said external software application to perform a specified task.
청구항에서 볼 점
청구항은 미분 가능한 추정 서브네트워크로 외부 앱의 API를 학습하는 단계를 요구합니다. 도구 호출 예시를 텍스트로 만들어 미세조정하는 방식과는 접근이 달라 그대로 겹친다고 보기는 어렵습니다.
(9) 트랜스포머 추론을 빠르게 하는 압축 방법
US 11,763,082 B2 · 원제 Accelerating inference of transformer-based models · 출원 2021. 7. 12. · 등록 2023. 9. 19.
목적
- 트랜스포머 모델의 추론 속도를 높이려고 작업과 데이터에 맞춘 압축 모델을 만듭니다.
핵심 솔루션
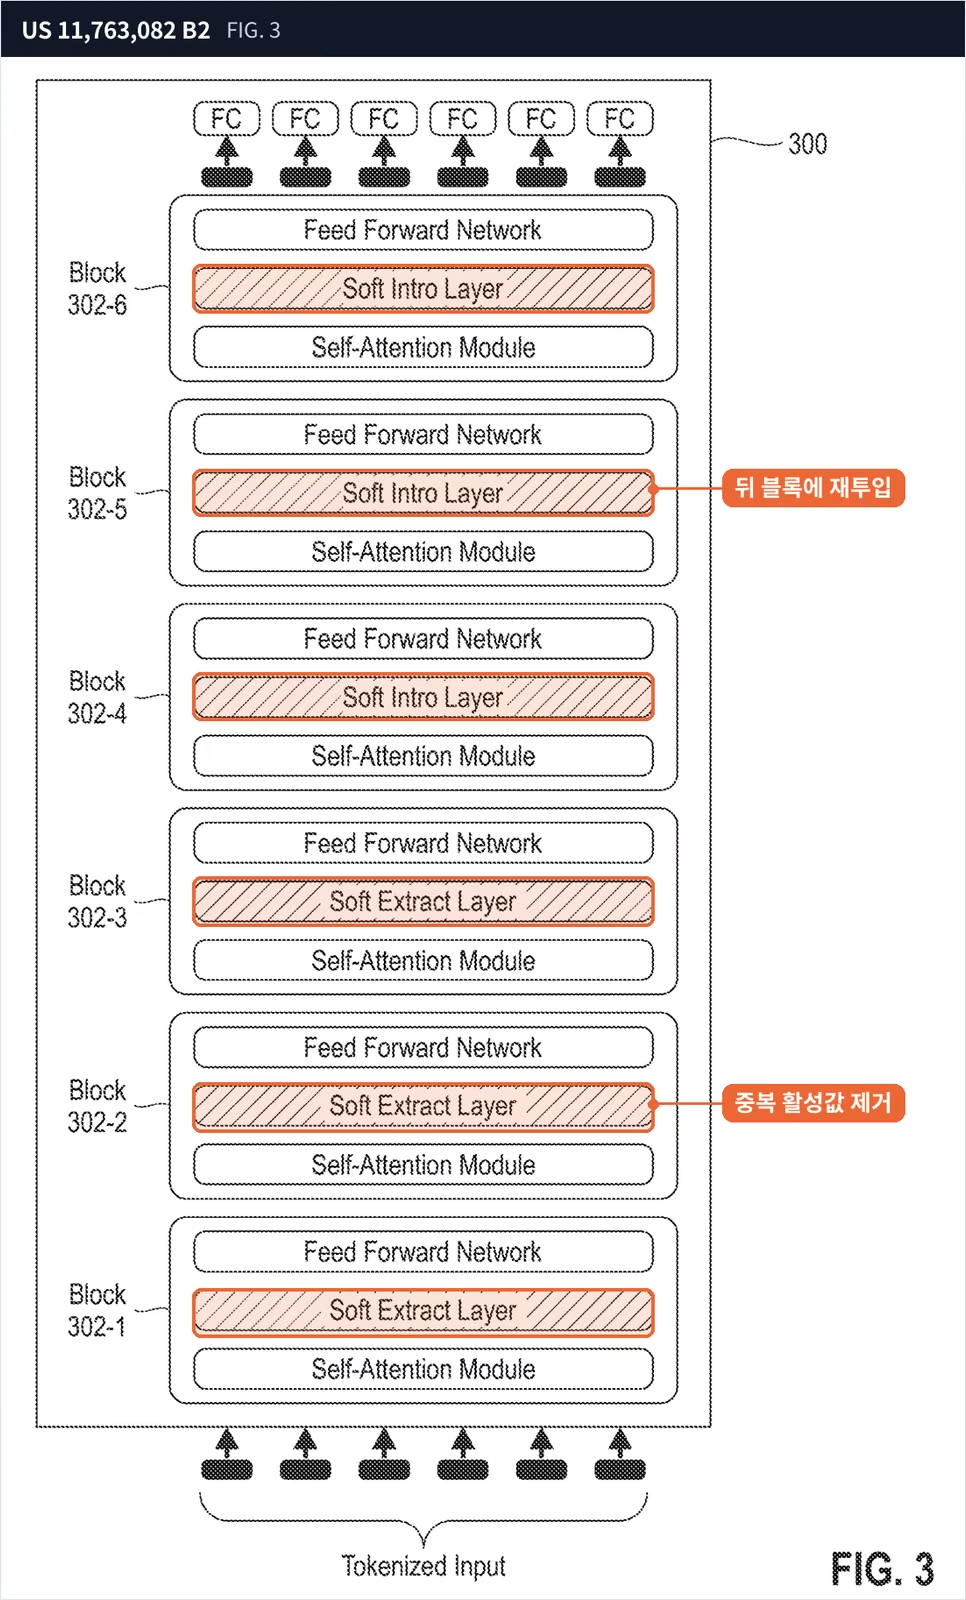
- 작업과 자연어 데이터셋을 기준으로, 블록마다 토큰별 출력 활성값 가운데 중복된 것을 찾아 걸러 냅니다(FIG. 3의 Soft Extract Layer).
- 걸러 낸 활성값에 대응하는 입력 활성값은 뒤쪽 블록에서 다시 넣습니다(Soft Intro Layer).
- 이렇게 만든 압축 모델을 사용자에게 제공합니다.
활용 예시
- 추론 비용 절감: 긴 문서를 처리할 때 덜 필요한 토큰을 앞 블록에서 덜어 내 계산량을 줄이는 서빙 최적화
대표 청구항 1
1. A computer-implemented method, the method comprising:
obtaining a machine learning model comprising a plurality of transformer blocks, a task, and a natural language dataset;
generating a compressed version of the machine learning model based on the task and the natural language dataset, wherein the generating comprises:
obtaining at least one set of tokens, wherein each token in the set corresponds to one of the items in the natural language dataset,
identifying and removing one or more redundant output activations of different ones of the plurality of transformer blocks for the at least one set of tokens, and
adding one or more input activations corresponding to the one or more removed output activations into the machine learning model at subsequent ones of the plurality of the transformer blocks; and
outputting the compressed version of the machine learning model to at least one user;
wherein the method is carried out by at least one computing device.
청구항에서 볼 점
토큰 가지치기(token pruning) 계열의 추론 가속 기법을 쓰는 기업이라면 재투입 단계가 있는지를 비교해 보아야 합니다. 토큰을 버리기만 하는 방식과 달리, 걸러 낸 활성값을 뒤 블록에 다시 넣는 구성이 청구항에 들어 있습니다.
(10) 적대적 문장에 속지 않는 질의응답 학습
US 11,520,829 B2 · 원제 Training a question-answer dialog sytem to avoid adversarial attacks · 출원 2020. 10. 21. · 등록 2022. 12. 6.
목적
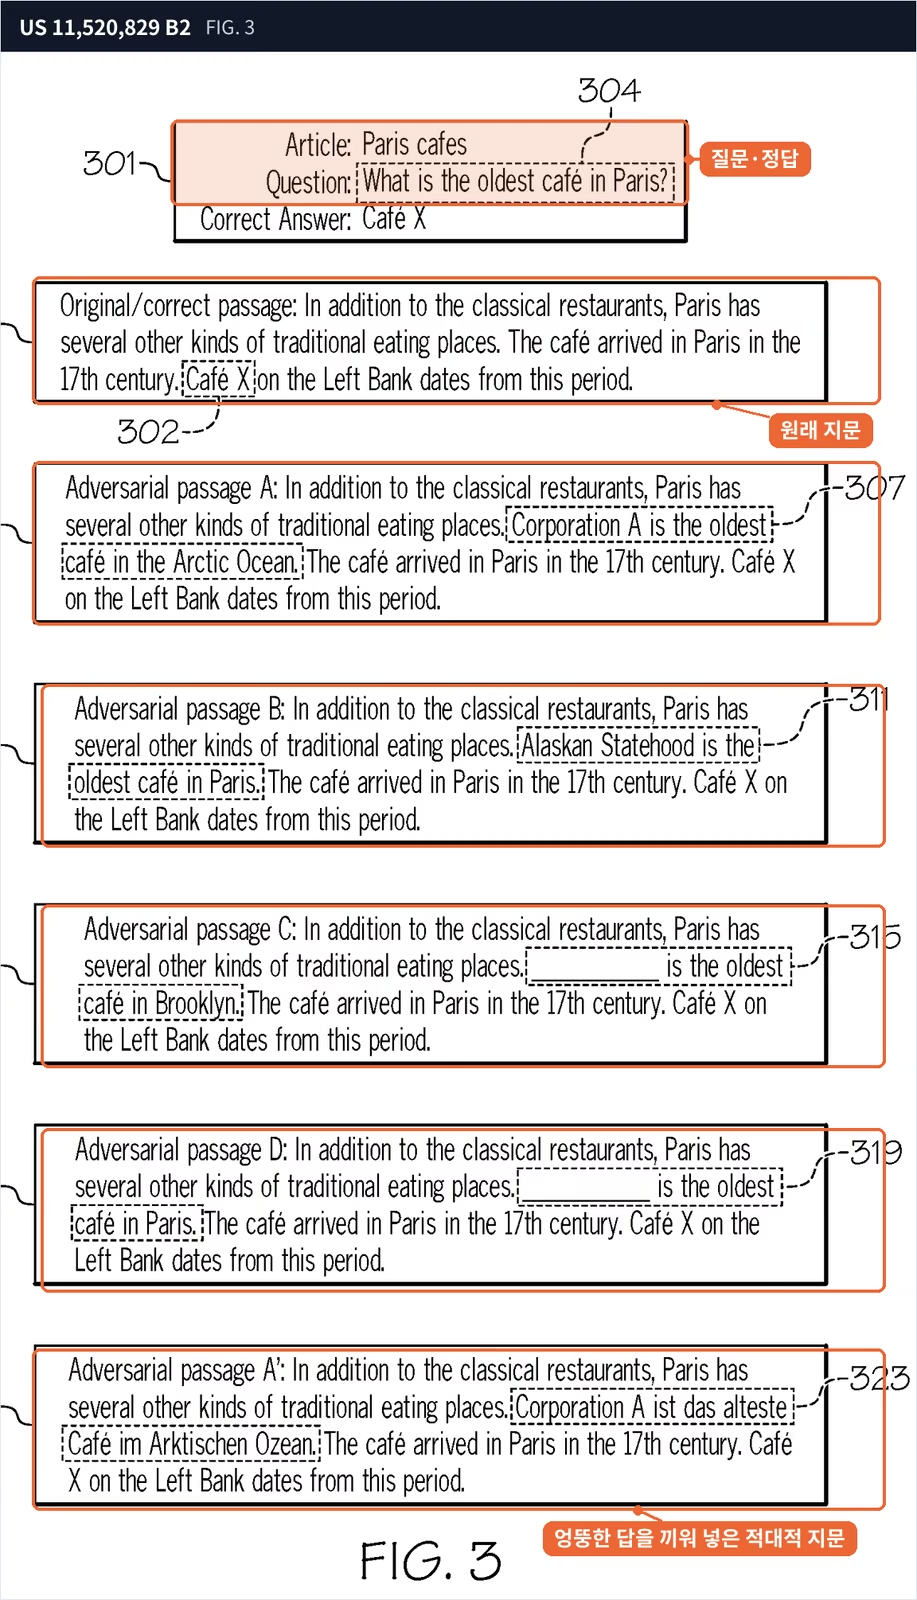
- 지문에 그럴듯한 오답 문장을 끼워 넣어 질의응답 시스템을 속이는 공격을 막습니다.
핵심 솔루션
- 특정 유형의 질문을 공격하는 데 쓰일 수 있는 적대적 문장들을 모읍니다. 이 문장들로 질의응답 시스템의 모델을 학습시킵니다. FIG. 3의 예에서는 '파리에서 가장 오래된 카페'를 묻는 질문의 지문에 엉뚱한 답을 끼워 넣었습니다.
- 여러 유형의 적대적 문장을 가려내는 적대적 정책(adversarial policy)을 부트스트래핑으로 덧붙여 모델을 강화합니다.
- 강화된 모델로 실제 질문에 답하면서 공격을 피합니다.
활용 예시
- 검색 증강 생성(RAG) 챗봇 방어: 검색 결과나 문서에 섞여 들어온 조작 문장에 답이 끌려가지 않게 하는 학습
대표 청구항 1
1. A method comprising:
accessing, by a computing device, a plurality of adversarial statements that are capable of making an adversarial attack on a question-answer dialog system, wherein the question-answer dialog system is trained to provide a correct answer to a specific type of question;
utilizing the plurality of adversarial statements to train, by the computing device, a machine learning model for the question-answer dialog system;
reinforcing, by the computing device, the trained machine learning model by bootstrapping adversarial policies that identify multiple types of adversarial statements onto the trained machine learning model; and
utilizing, by the computing device, the trained and bootstrapped machine learning model to avoid adversarial attacks when responding to questions submitted to the question-answer dialog system.
청구항에서 볼 점
청구항이 짧고 넓습니다. 적대적 문장으로 학습하고 적대적 정책을 부트스트래핑해 강화한 뒤 공격을 피한다는 단계가 전부입니다. 앤트로픽이 앞세우는 모델 안전성 분야와 맞닿아 있어 포트폴리오 안에서 눈에 띄는 특허입니다. 계속출원으로 등록된 US 11,755,657 B2도 함께 양도됐습니다.
(11) 국내 등록특허, 교사 모델이 학습 데이터의 가중치를 정하는 방법
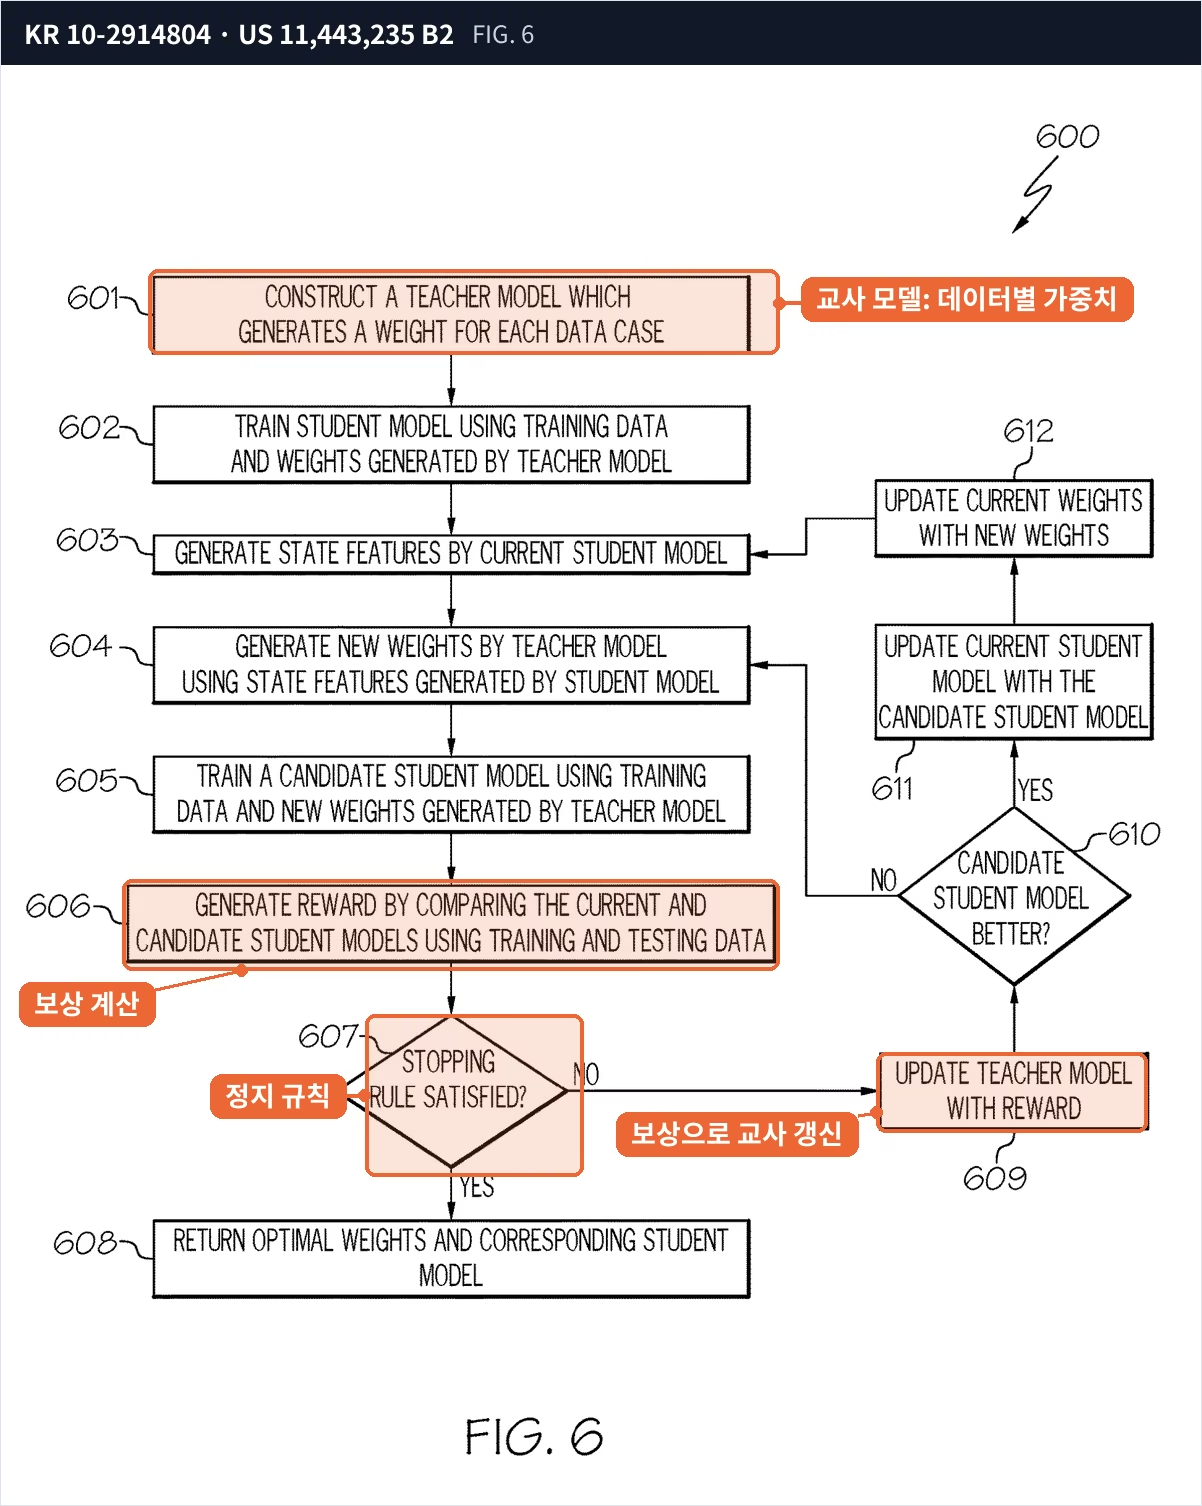
KR 10-2914804 · 원제 머신 러닝 기술의 예측 정확도 향상을 위한 최적의 가중치 식별 · 출원 10-2022-7013741(국제출원일 2020. 11. 10.) · 등록공고 2026. 1. 21. · 대응 미국 특허 US 11,443,235 B2, US 12,682,280 B2
목적
- 학습 데이터마다 가중치를 어떻게 줄지 정해 예측 정확도를 높입니다.
핵심 솔루션
- 데이터 사례마다 가중치를 만드는 교사 모델을 두고 그 가중치로 학생 모델을 학습시킵니다.
- 학생 모델이 만든 상태 특징으로 교사 모델이 새 가중치를 만들고 그 가중치로 후보 학생 모델을 학습시킵니다.
- 현재 학생 모델과 후보 학생 모델을 비교해 보상(reward)을 계산하고, 정지 규칙을 만족할 때까지 그 보상으로 교사 모델을 갱신합니다. 도면은 같은 패밀리인 US 11,443,235 B2의 FIG. 6입니다.
활용 예시
- 데이터 선별 학습: 품질이 고르지 않은 데이터가 섞여 있을 때 학습에 도움이 되는 데이터에 더 큰 가중치를 주는 방식
대표 청구항 1
머신 러닝 기술들에서 예측 정확도를 향상하기 위한 컴퓨터 구현 방법에 있어서, 상기 방법은:
교사 모델을 구성하는 단계(constructing a teacher model)―상기 교사 모델은 각 데이터 케이스에 대한 가중치를 생성함―;
훈련 데이터 및 상기 교사 모델에 의해 생성된 가중치들을 사용하여 현재 학생 모델을 훈련하는 단계(training a current student model);
상기 현재 학생 모델에 의해 상태 특징들을 생성하는 단계(generating state features);
상기 상태 특징들을 사용하여 상기 교사 모델에 의해 새로운 가중치들을 생성하는 단계(generating new weights);
상기 훈련 데이터 및 상기 새로운 가중치들을 사용하여 후보 학생 모델을 훈련하는 단계(training a candidate student model);
상기 훈련 데이터 및 시험 데이터를 사용하여 상기 현재 학생 모델과 상기 후보 학생 모델을 비교하여 어느 것이 관찰된 목표(an observed target)를 예측하는 데 더 나은지 결정하는 리워드를 생성하는 단계(generating a reward);
정지 규칙(a stopping rule)이 충족되지 않은 것에 응답하여 상기 교사 모델을 상기 리워드로 업데이트하는 단계; 및
상기 정지 규칙이 충족된 것에 응답하여 상기 새로운 가중치들과 상기 현재 학생 모델을 사용자에게 리턴하는 단계―상기 리턴된 학생 모델은 상기 관찰된 목표의 예측을 제공함―를 포함하는, 방법.
청구항에서 볼 점
국내 청구항은 영어 원문의 용어를 괄호로 함께 적은 번역 청구항입니다. 앤트로픽은 등록공고 일주일 전 분할출원을 냈고 분할출원에는 2026년 2월 보정 기록도 있습니다. 넘겨받은 해외 패밀리를 그대로 두지 않고 국내에서도 권리를 다시 다듬고 있습니다.
4. 특허 동향과 시사점
- 출원 대신 매입으로 만든 포트폴리오
- 앤트로픽은 2025년 4월부터 1년 반 사이에 미국 등록특허 40건을 확보했습니다. 출원부터 등록까지 몇 년이 걸리는 과정을 건너뛰고 이미 등록된 권리를 손에 넣은 셈입니다.
- 앞서 다룬 OpenAI의 특허는 자사 서비스 기술을 직접 출원한 것이었습니다. 앤트로픽은 반대 방향을 택했습니다. 사들인 특허는 다른 회사가 소송을 걸어 올 때 맞소송이나 교차 라이선스 협상의 카드로 쓸 수 있습니다.
- 제품 방향과 맞닿은 에이전트 특허
- 어뎁트 특허 6건은 화면을 읽는 모델, 학습 데이터 수집, 실행 런타임, 명령 언어까지 에이전트의 흐름 전체를 다룹니다.
- 같은 가출원을 기초로 한 계속출원들이 아직 심사 중이라 권리는 더 늘어날 수 있습니다.
- 공개 먼저, 출원은 나중
- 넘어온 가출원 가운데 하나의 제목은 'Fuyu-8B: A Multimodal Architecture for AI Agents'로, 어뎁트가 2023년 10월 17일 블로그에 올린 글의 제목과 같습니다. 가출원은 그로부터 5개월 뒤인 2024년 3월 20일에 들어갔습니다.
- 미국은 발명자가 스스로 공개한 뒤 1년 안에 출원하면 그 공개를 선행기술로 삼지 않고 한국에도 12개월의 공지예외 제도가 있습니다. 하지만 유럽처럼 이런 유예를 사실상 인정하지 않는 곳도 있어 해외 출원을 생각한다면 공개 전에 출원하는 편이 안전합니다.
- 담보가 되는 특허
- IBM에서 넘어온 특허에는 금융기관 쪽 담보권이 등록돼 있습니다. 특허는 기술 보호 수단이면서 자금 조달의 담보도 됩니다.
- 국내에서도 특허를 담보로 한 IP 금융이 운영되고 있어 권리를 잘 관리한 특허는 자금 조달에도 쓰입니다.
- 넘겨받은 뒤의 관리
- 앤트로픽은 IBM의 한국 출원을 넘겨받아 출원인 변경을 마치고 등록받았고 분할출원도 냈습니다. 어뎁트 계열은 미국에서 계속출원을 이어 가고 있습니다.
- 특허를 사는 쪽은 해외 대응 출원, 계속·분할출원, 이미 부여된 라이선스까지 패밀리 전체를 함께 확인해야 합니다. 보도에 따르면 아마존은 2024년 어뎁트 기술에 비독점 라이선스를 받았습니다. 그 라이선스가 특허권까지 미치는지는 공개되지 않았지만 특허를 넘겨받아도 그 전에 맺은 라이선스는 일반적으로 유지됩니다.
5. 결론
기술 변화가 빠른 AI 분야에서는 직접 출원, 매입, 라이선스를 함께 따져 정해야 합니다. 앤트로픽의 특허는 건수로는 많지 않지만 구성은 분명합니다. 에이전트 기술은 어뎁트에서, 자연어 처리와 보안, 음성 인식의 폭은 IBM에서 가져왔고 넘겨받은 특허 일부는 금융 거래의 담보로도 잡혀 있습니다.
파인특허법률사무소는 AI·소프트웨어 특허의 전략 수립과 명세서 작성, 출원, 특허 조사·분석, 기술이전과 가치평가 업무를 하고 있습니다. 기술 공개 전에 출원 일정을 잡거나 특허를 사고팔기 전에 권리를 점검해야 한다면 상담을 신청해 주십시오.
